Two snapshots, one calibrated screening result
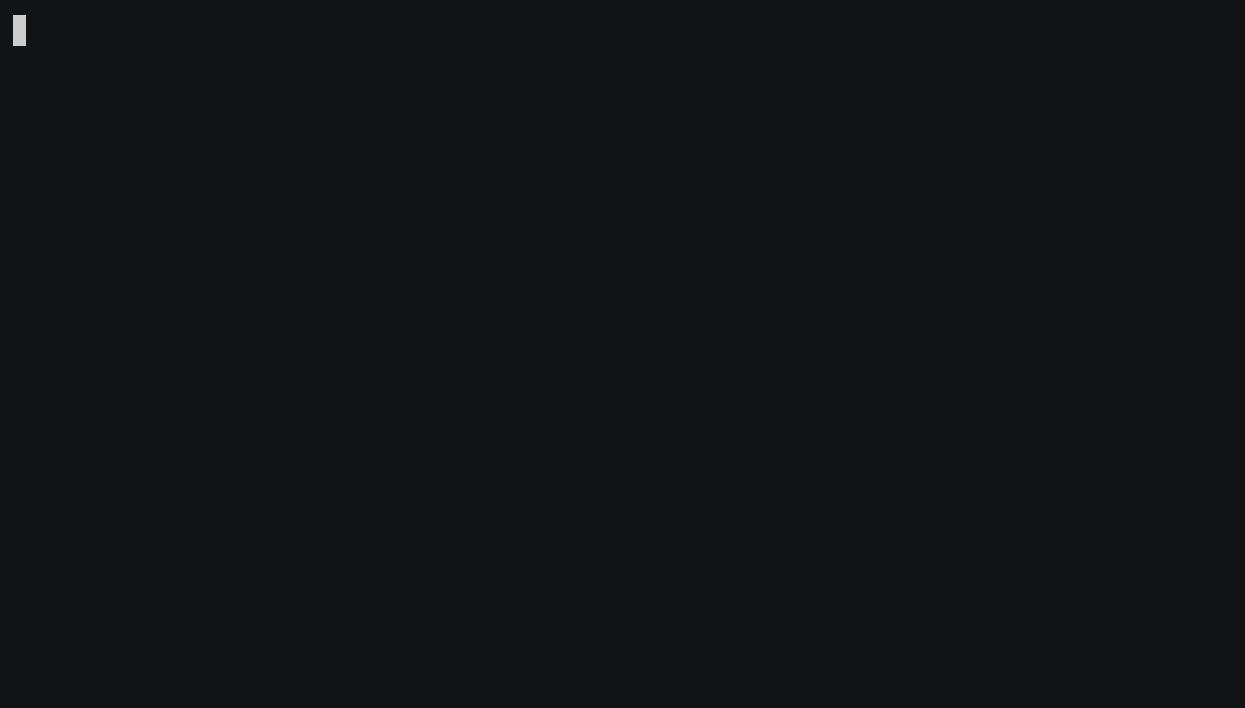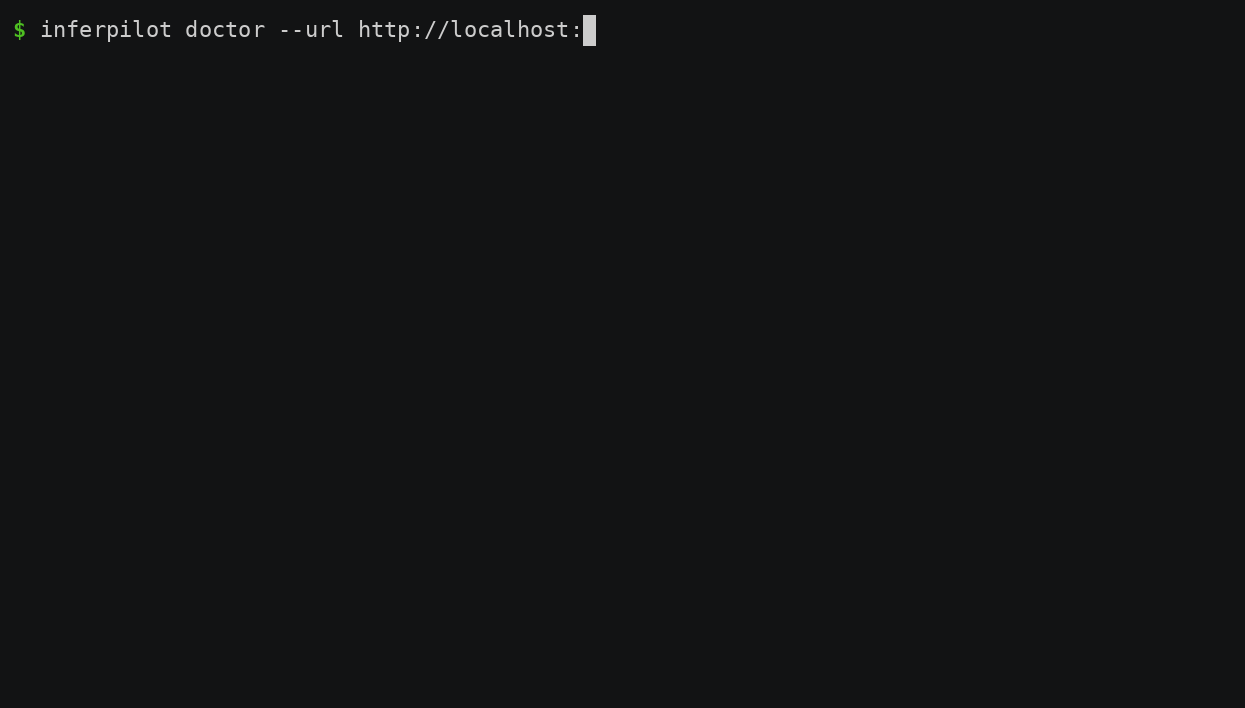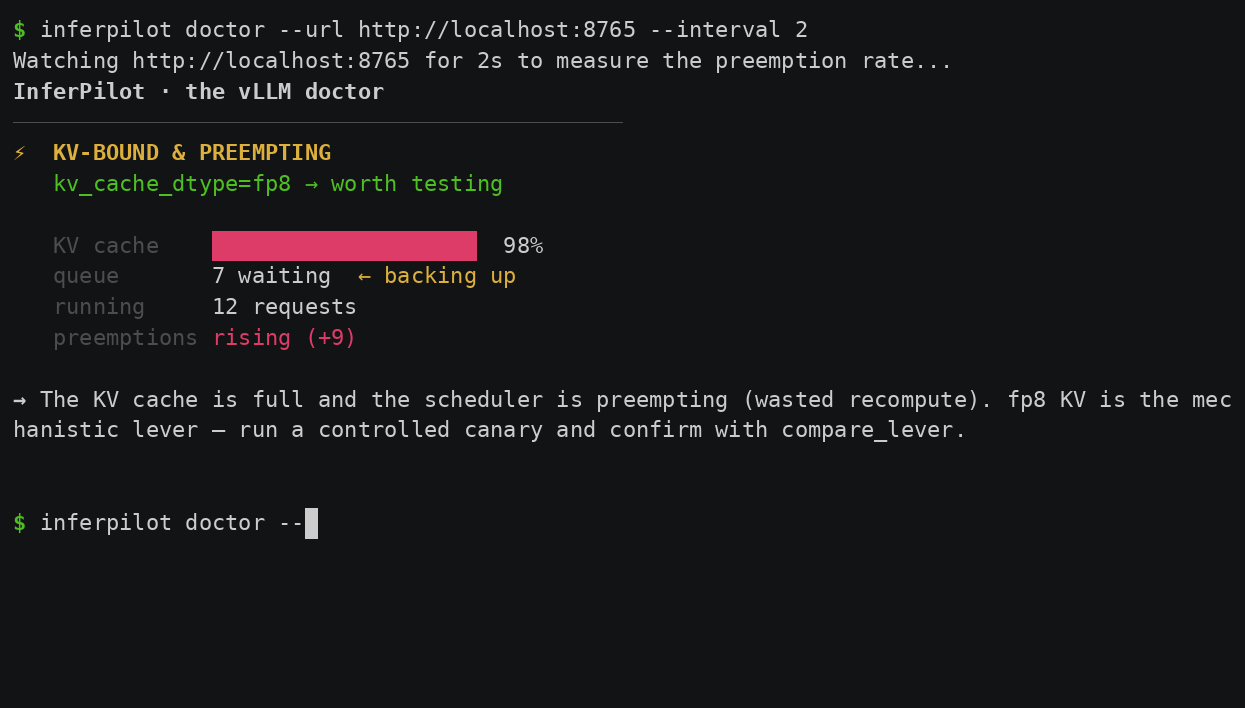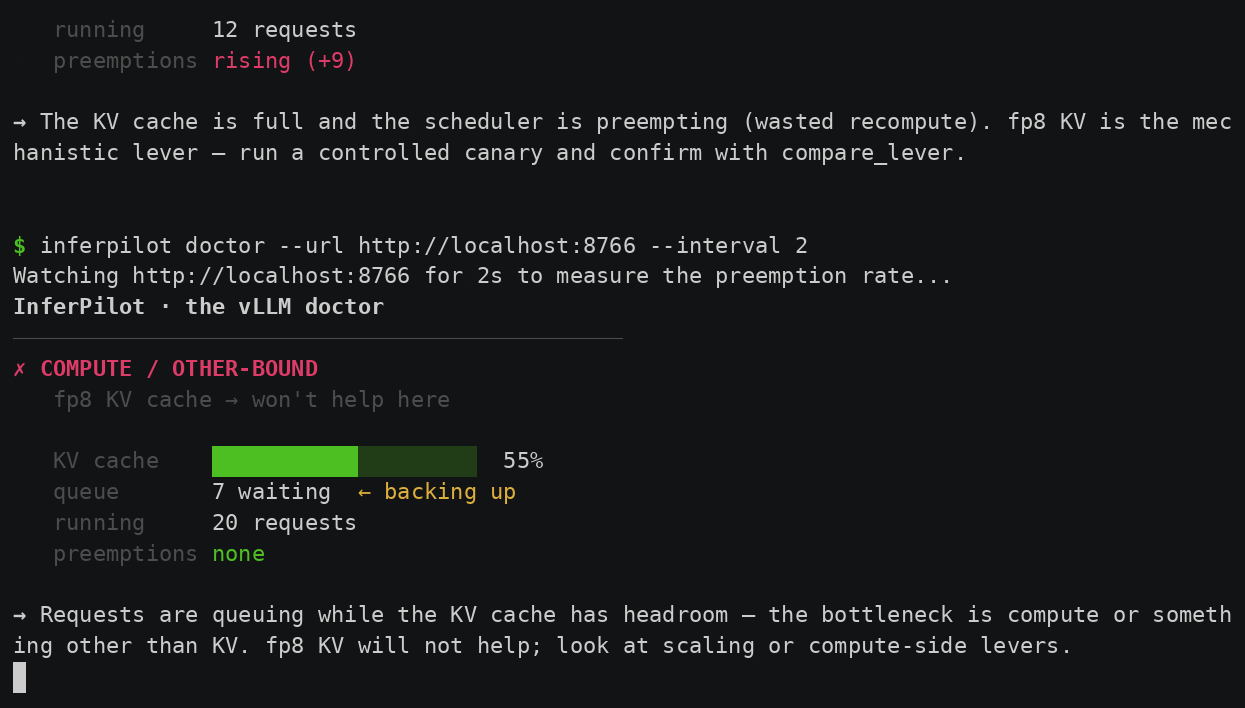
GPU utilization sits near 100% whether you're genuinely compute-bound or just thrashing on KV cache. It can't tell these apart. Preemptions and queue depth provide a useful screening signal, which InferPilot uses to choose the next controlled experiment.
fp8 KV cache → worth testing
KV cache is full and the scheduler is preempting. Test fp8 under the same traffic and SLO.
prioritize compute or scaling tests
A queue is building while KV has headroom, so this snapshot does not support KV capacity as the limit.
watch the preemption counter
KV is full but not preempting yet. fp8 is pre-emptive insurance, not a measured win.
no KV lever warranted
KV has headroom and nothing is queuing. If latency matters, that's a separate, low-load question.
Try the diagnosis
Move the signals your vLLM server would report and watch the verdict change. Two servers can show the same ~99% GPU utilization and get opposite answers — that's the whole point.
Observed signals
What a measured window of your server reports.
InferPilot verdict
Recomputed live — or it abstains.
Measured, not hypothetical
A paired study on Qwen2.5-3B (A10G, vLLM 0.29.0) using an exact recomputed-token counter added to vLLM (an open PR to vLLM core). In the preempting regime, fp8 drove recomputed tokens to zero and throughput up. Total GPU cost: $0.81.
Honest caveat: in the later preregistered 7B study, throughput improved 33.6% on the pressured workload and 0.2% on the control, but recomputation did not fall as registered. The verdict was INCONCLUSIVE, not a mechanism win. Read the full result.
Install
Pure Python, pydantic-based. The diagnosis path needs no GPU and no vLLM install.
Run with zero install
uvx inferpilot doctor --url …Keep it around
uv tool install inferpilotClassic
pip install inferpilotThen the daily loop: doctor to glance,
doctor --watch to monitor, capacity to turn a rate sweep into an SLO-capacity ceiling,
a $/token, and an action plan. No server yet? uvx inferpilot demo exercises the complete
decision contracts using clearly labelled synthetic metadata.